Frontier AI on your infrastructure.
Try frontier models without buying GPUs. If it fits your use case, we deploy it on your infrastructure with our gateway. Integrates with base URL and API key.
No prompt retention
We do not store what you send or what the model returns
Usage metrics only
Tokens, latency and inference times to improve the deployment
US infrastructure
Everything runs in the United States with compatible endpoints
Validate before buying GPUs.
Validate your use case without buying hardware. We give you access to our gateway with frontier models for 4 days.
- 3 curated models plus specialized option up to 14B
- Gateway managed by us
- Workspaces and API keys per user
- Onboarding and integration included
- 4 days of unlimited use with fair use
- Usage report and hardware recommendation
The model on your infrastructure. Dedicated gateway under your control, support and optional fine tuning.
- Any model, no size limit
- Dedicated gateway on your infrastructure
- Gateway license included
- Support by plan
- Fine tuning quoted separately when needed
- Trained models remain yours
Fast Deploy uses fair use to simulate production. If you need a small specialized model we train it inside the same Fast cycle when it applies.
From trial to deployment.
Activate Fast Deploy
With 50% upfront we provision GPUs and create your workspace in Kronos Platform. Each user generates their own API key.
Integrate your stack
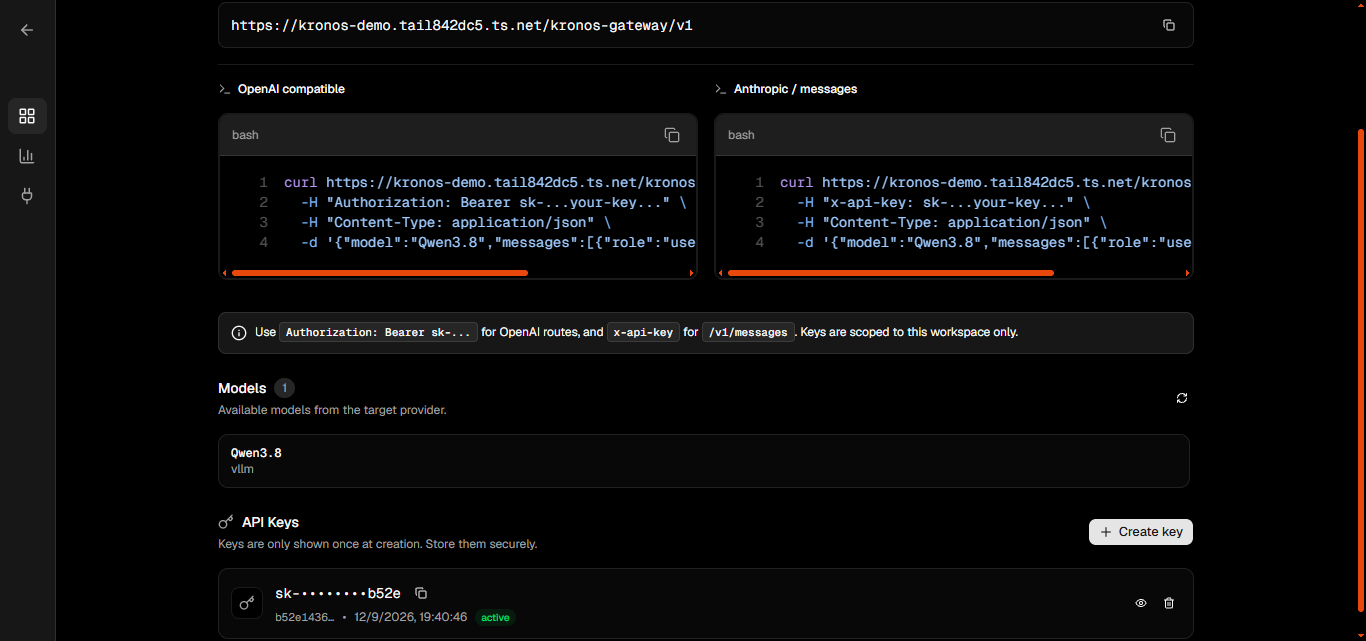
We help you connect your tools. Two values and you are in: base URL and API key. Compatible with OpenAI and Anthropic.
4 days of real usage
Unlimited usage to measure integration, quality and reasoning. We simulate a production deployment without buying hardware.
Report and move to Deploy
We cut access on day 5 and deliver the usage report with hardware recommendations. If it makes sense, we move to Kronos Deploy on your infrastructure.
Day 5 deliverable
A report to decide with data if you move to your infrastructure.
- Total and per model input and output tokens
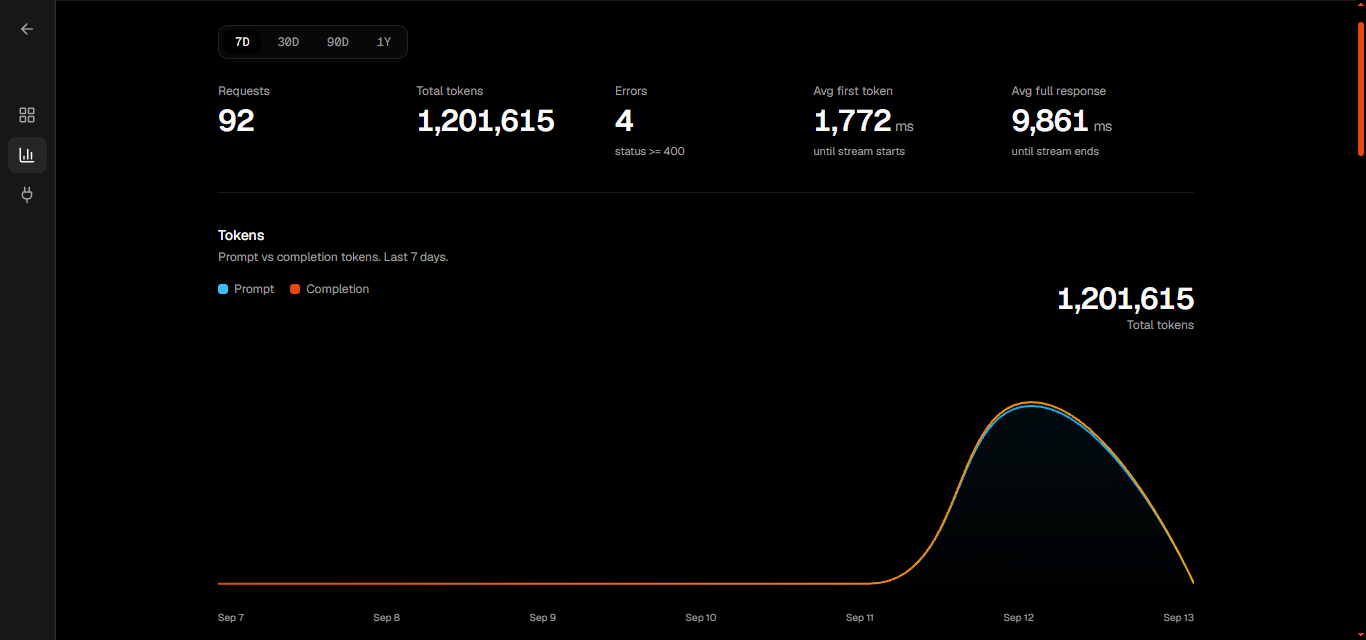
- Requests, errors and daily activity
- p50, p90, p99 latency and time to first token
- Integration checklist completed
- Hardware recommendation and Kronos Deploy quote
Three models ready to try.
264k context and visible traces.
Qwen 3.8
DeepSeek V4 Flash Vision
GLM 5.3 Flash
Need something specific? In Fast we can train a specialized model up to 14B as part of the cycle.
Try these modelsAccess control for the model.
Workspaces per company
Isolation per workspace. Each one points to its deployment and keeps metrics separate.
API keys per user
Each person creates their own key. Hidden by default, you see it only after a notice.
OpenAI and Anthropic
The same gateway speaks both protocols. Switch SDKs without switching infra.
Real streaming
Streaming responses with no buffering. Built for agents and production chat.
Metrics per request
Requests, input and output tokens, latency and time to first token.
Fast managed, Deploy yours
In Fast we manage it. In Deploy it runs on your infra under your control.
Your tools already work.
Qwen 3.8 in use.
Tell us about your use case.
Before you reach out.
What does Kronos Fast Deploy include?
GPU provisioning, workspace creation in Kronos Platform, onboarding to integrate your stack and 4 days of unlimited use with fair use to measure integration, quality and reasoning.
How does the $2,500 payment work?
50% upfront before provisioning and 50% on deployment complete. You can validate without risk and keep commitment on both sides.
What happens on day 5?
We cut access. We deliver a report with input and output tokens, requests, errors, p50 and p90 latency, time to first token and hardware recommendation for Kronos Deploy.
What does unlimited use mean?
You can use the models freely within fair use that simulates production. If usage breaks that balance we discuss it to keep the deployment stable for everyone.
Do you store what our users send?
No. We do not retain prompts or responses. We only keep usage metrics such as tokens, latency and inference times to improve the deployment.
Where does Fast Deploy run?
In the United States. We define the data processing and support framework for your case on top of that.
Which tools does it integrate with?
Any tool that speaks OpenAI or Anthropic. We have guides for OpenAI SDK, Claude Code, Codex, opencode, Cursor, Continue, Open WebUI, LangChain, Vercel AI SDK, n8n and more. Base URL with /v1 for OpenAI and without /v1 for Claude Code.
Can you train a small model inside Fast Deploy?
Yes. If your case needs it, we train a specialized model up to 14B inside the Fast Deploy cycle. For larger models we move to Kronos Deploy.
How is Kronos Deploy quoted?
Based on GPUs and topology, gateway license and support. If fine tuning is needed, we add the compute required on our infrastructure.
Do we own the model and data?
Yes. The trained model weights and your data are yours from the start.
What does the gateway include?
Workspaces per company, member control, API keys per user hidden by default and shown only with notice, OpenAI and Anthropic compatibility, streaming and metrics per workspace.